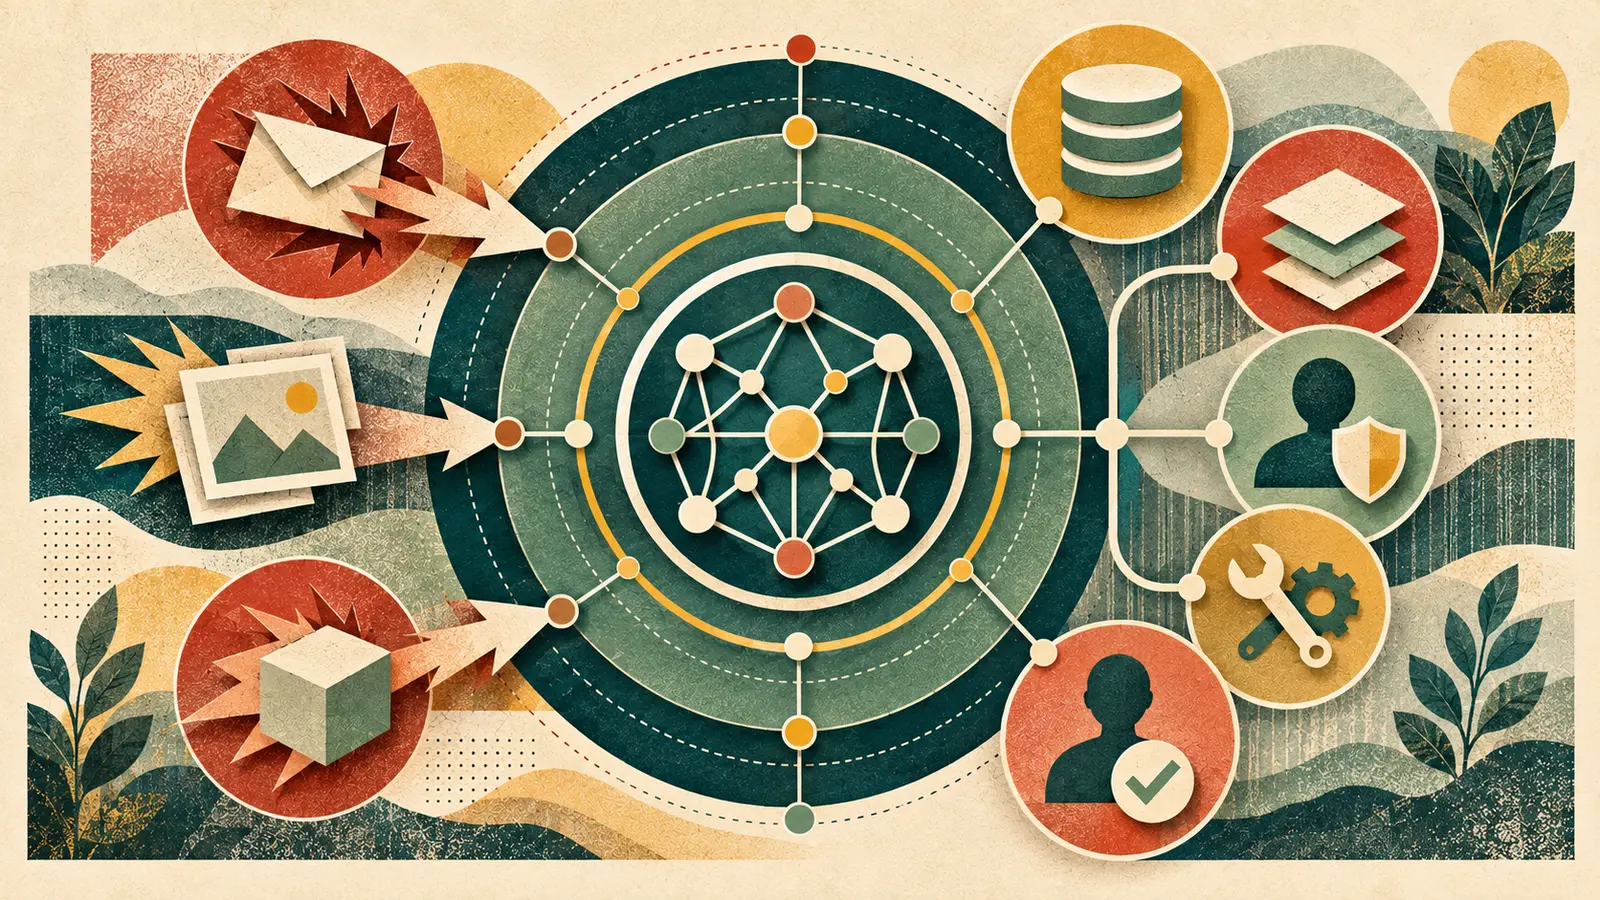
NIST’s draft SP 2400-102e2026 gives security, engineering, and governance teams a shared vocabulary for adversarial machine learning. Its value is not in producing another compliance checklist. It is in helping teams describe which AI system is being attacked, at what lifecycle stage, with what attacker knowledge and capabilities, toward which objective, and with which consequences.
What NIST published
The initial public draft, “Adversarial Machine Learning: A Taxonomy and Terminology of Attacks and Mitigations,” was released on November 9, 2026, with comments open through December 18. NIST says the taxonomy covers machine-learning methods, lifecycle stages, attacker goals, objectives, capabilities, and knowledge, with particular attention to agentic systems.
This matters because an “AI attack” can describe very different events: poisoning training data, extracting a model, evading a classifier, manipulating retrieval context, abusing an agent’s tools, or causing an automated system to reveal information. A useful threat model must distinguish them.
Start with a system boundary
Choose one deployed model or agent and draw its real operational boundary. Include:
- training, fine-tuning, evaluation, and retrieval data;
- model artifacts, prompts, system instructions, and policy layers;
- identities used by people, services, plugins, and agents;
- tools the system can invoke and the permissions attached to them;
- memory, logs, vector stores, queues, and external APIs;
- human approvals and the decisions that bypass them;
- outputs that can trigger financial, operational, or security consequences.
Do not model only the model endpoint. For an agentic system, the most damaging path may be a legitimate tool call made with excessive privileges after manipulated context.
Describe the attacker precisely
Use the taxonomy to record what the attacker knows and controls. Can the attacker query the model? Supply documents to retrieval? Modify training data? Observe confidence scores? Create an account? Compromise a plugin? Influence another system whose output becomes trusted context?
Separate capability from intent. A user who can upload a document may unintentionally create prompt-injection exposure; a malicious insider may alter evaluation data; an external adversary may only have black-box access but can automate thousands of queries.
Map attacks to lifecycle stages
Threats differ before, during, and after deployment. Training-time poisoning can create hidden behavior that appears only under a trigger. Evaluation manipulation can make a weak control look effective. Inference-time evasion can cause misclassification. Retrieval manipulation can insert hostile instructions into context. Model extraction can turn a public interface into a source of proprietary behavior. Agent-tool abuse can convert misleading output into an external action.
For each scenario, write a short attack statement: “An actor with X access performs Y at lifecycle stage Z to achieve objective O, causing impact I.” This format is specific enough to test.
Attach mitigations to evidence
A control is not complete because it appears in an architecture diagram. Define the evidence that would demonstrate its operation:
- provenance and integrity checks for data and model artifacts;
- least-privilege service identities and scoped tool permissions;
- content isolation between untrusted inputs and system instructions;
- approval gates for high-impact actions;
- rate limits and anomaly detection for extraction attempts;
- adversarial testing tied to realistic attacker access;
- logging that connects model input, retrieved context, tool calls, approvals, and outcomes;
- a containment path that can disable a model, tool, credential, or data source.
Use the taxonomy in an operational workshop
- Select one production AI system with a meaningful business consequence.
- List its assets, trust boundaries, data sources, identities, and tools.
- Choose three plausible attacker positions: external user, compromised integration, and insider.
- Map scenarios to lifecycle stage, knowledge, capability, objective, and impact.
- Identify prevention, detection, containment, and recovery controls.
- Record the evidence each control should generate.
- Assign gaps to an owner and review date.
Common mistakes
Avoid treating prompt injection as the only AI security problem, listing theoretical attacks without an access path, or assuming that model-provider safeguards cover application permissions. Do not place all responsibility on the model team: identity, application, data, security-operations, legal, and business owners participate in the same system.
Practical checklist
- Inventory deployed models and agents, including owners and business impact.
- Map data, identities, tools, memory, and human approvals.
- Describe attacker knowledge, access, lifecycle stage, objective, and impact.
- Test least privilege and high-impact approval gates.
- Connect model and tool telemetry into incident response.
- Submit relevant feedback to NIST before December 18, 2026.
Read NIST’s draft announcement and publication details for the authoritative taxonomy and comment process.