CISA discontinued its weekly Vulnerability Bulletin at the end of fiscal year 2026 as part of a shift from severity-based vulnerability management to risk-based prioritization. New CVE records remain available through CVE.org, while CISA points defenders toward the Known Exploited Vulnerabilities catalog, cybersecurity alerts and advisories, and vendor security notices for actionable updates.
The operational consequence is positive: teams should stop treating a weekly list of high CVSS scores as a patch plan. A defensible queue combines exploitation evidence, asset exposure, business impact, technical reachability, and the availability of reliable remediation.
Keep discovery separate from priority
A vulnerability feed answers “what exists?” It does not answer “what should this organization fix first?” Continue ingesting CVE data from scanners, software inventories, vendor advisories, and asset tools, but do not let feed order determine remediation order.
CISA’s bulletin page recommends the KEV catalog, CISA alerts, and vendor notices as risk-oriented sources. Each brings a different signal: KEV indicates known exploitation, alerts add campaign context, and vendor bulletins define affected configurations and fixed versions.
Use a small set of auditable signals
A practical priority model can use six inputs:
- Known exploitation: KEV inclusion, vendor confirmation, or credible incident evidence.
- Reachability: internet exposure, partner access, or a realistic internal attack path.
- Asset consequence: identity, edge, management, data, safety, and revenue impact.
- Exploitability: required privileges, user interaction, configuration preconditions, and exploit maturity.
- Control strength: segmentation, allowlisting, isolation, monitoring, and other verified compensating controls.
- Remediation confidence: availability of a supported patch, configuration change, or replacement path.
Keep the model understandable. A complex score that nobody can explain will be ignored during an incident. Each urgent item should display the evidence behind its rank, not only a number.
Create action lanes, not one endless list
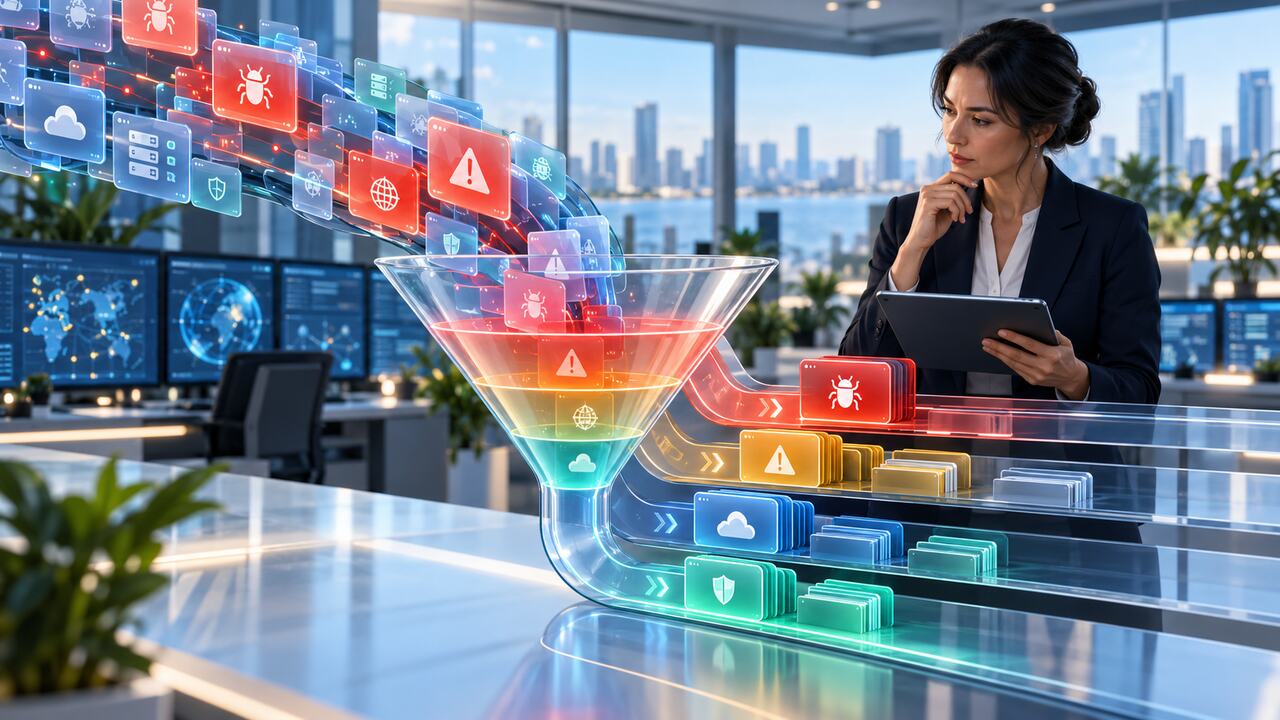
Divide the queue into operational lanes. “Act now” covers exploited vulnerabilities on reachable or high-impact assets. “Validate and schedule” covers serious issues with plausible exposure but no evidence of exploitation. “Monitor” covers items awaiting vendor clarification, detection logic, or a stable fix. “Accept or retire” contains unsupported systems and explicit risk decisions.
Every lane needs a service level, owner, and exit condition. For an exploited edge vulnerability, closure may require both patching and compromise assessment. For a library flaw, closure may require proving that the vulnerable function is unreachable. The definition of done should match the threat, not the scanner status.
Connect vulnerability and asset data
Prioritization fails when the security team knows the CVE but not where the product runs. Build reliable joins among software inventory, cloud accounts, network exposure, identity ownership, and business service maps. Include standby nodes, images, containers, appliances, and disaster-recovery systems.
Where ownership is missing, assign an escalation path rather than silently downgrading the item. “Unknown owner” increases risk because remediation is less likely and incident coordination will be slower.
Add temporal signals without chasing noise
Risk changes over time. A vulnerability may move from monitor to act-now when exploitation is confirmed, public code appears, an asset becomes externally reachable, or a vendor releases a reliable fix. Conversely, validated non-reachability or removal of the affected component can reduce priority.
Automate these state changes where the data is strong, but require human review for destructive or business-disruptive actions. Store the previous rank and the evidence that changed it. This creates an audit trail and helps teams learn which signals actually predicted urgent work.
Make exceptions expire
An exception should state the affected assets, rationale, compensating controls, approving risk owner, and expiry date. Re-evaluate it when exploitation status changes, a patch appears, an asset becomes internet-facing, or the business impact increases.
Do not allow “not exploitable” to become a permanent label without evidence. Record the configuration test, code path, network boundary, or product feature that supports the conclusion. Re-run that test after upgrades and architecture changes.
Measure risk reduction
Useful metrics include time to identify affected assets, time to containment, time to verified remediation, percentage of KEV exposure with complete ownership, and number of reopened findings caused by incomplete inventory. A raw count of closed CVEs can reward teams for fixing easy low-impact issues while dangerous exposure remains.
The end of the weekly bulletin is not the end of weekly review. Replace it with a short decision meeting that examines new exploitation evidence, changed exposure, overdue actions, and blocked remediations. The output should be a ranked, owned action queue—not a PDF archive.